“Context graph” became the term of the quarter. The idea is sound: connect the company’s entities, definitions, decisions and documents into one graph, and an agent can answer questions with the whole business in view. Analysts publish hype cycles about it, and every database vendor has a slide.
Read the original essay that popularised the term, from Foundation Capital in December 2025, and search it for the word “permission”. It appears zero times in the roughly 31 places the essay says “context graph”. That omission is the subject of this post.
A context graph is a materialised view over a company’s documents and data. Materialised views go wrong in two ways, and both are well known to anyone who has maintained a warehouse: they were computed with someone’s permissions, and they were computed at a point in time.
It was built with someone’s permissions
When a central index is built, a crawler reads sources using some identity. The question that decides everything is what happens to access control after that. The vendors’ own documentation shows four seams.
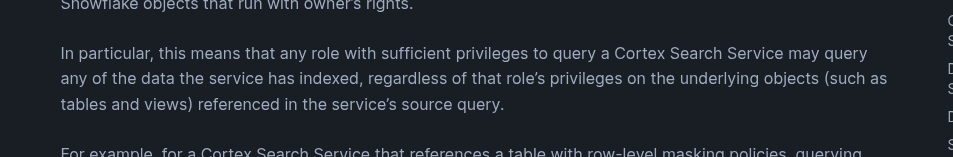
The index runs with the builder’s rights. Snowflake’s documentation for Cortex Search says that “any role with sufficient privileges to query a Cortex Search Service may query any of the data the service has indexed, regardless of that role’s privileges on the underlying objects.” Databricks’ vector search takes a similar stance: row and column permissions are not supported, and you can build your own application-level ACLs with a filter API.
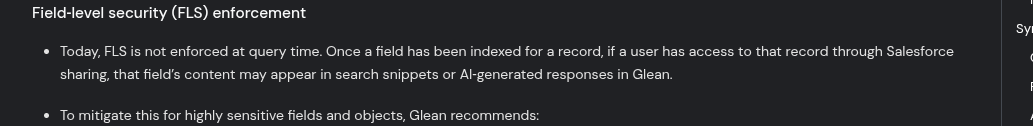
Permissions are copied at a coarser grain than the source. Glean’s Salesforce connector documentation is blunt: “Today, FLS is not enforced at query time. Once a field has been indexed for a record, if a user has access to that record through Salesforce sharing, that field’s content may appear in search snippets or AI-generated responses in Glean.” Cognee’s docs say permissions are defined at the dataset level, never for individual documents.
The permission copy lags behind the source. The same Glean page says Salesforce share records are crawled “with a full scan on a regular schedule (by default, hourly) because Salesforce’s APIs do not expose deleted share records incrementally.” Authorisation systems have a name for this failure. SpiceDB calls it the New Enemy Problem: if a relationship changes and the caches have not been updated, there is a risk of returning incorrect permission information.
Derived summaries have no single correct ACL. A graph answer is synthesised from many sources, and some of the readers of the answer may not be allowed to see some of the sources. A request filed on 8 October on Cognee’s tracker puts it plainly: post-filtering is “unsafe for graph answers, which are already synthesized from denied sources.” An arXiv paper from 5 October measured the result for agent memory. Naive content-gated memory leaked 18.8 to 25.5% of the time across departments in six experiments. Gating retrieval on lineage removed that leakage, but only when 75 to 90% of the lineage was recorded.
The open-source frameworks mostly leave the problem to you. When a contributor proposed fact-level access control for Graphiti, the maintainer replied on 21 September: “We’re not looking to add this to Graphiti at this time.”
One correction to a popular framing. Microsoft 365 Copilot is not a case of a graph that flattens permissions. Microsoft says it “only surfaces organizational data to which individual users have at least view permissions”, checked at query time. Copilot’s documented problems are different: source permissions that were already too broad, policy layers that were skipped, and untrusted content that the user is allowed to read. An index can be permission-correct and still unsafe. That is a separate failure from the one in this section.
It was built at a moment in time
The second failure is quieter. The graph describes the company as it was when the crawl finished.
Anthropic’s data team put numbers on it. Their analytics agent needs written “skills” that describe the data model, and “without active maintenance they’re wrong within weeks. We watched our offline accuracy drift from ~95% at launch to ~65% over a month.” Their fix was organisational. The skill files live in the same repository as the transformation models, so the pull request that changes a model also updates the document that describes it. I covered that post in an earlier essay.
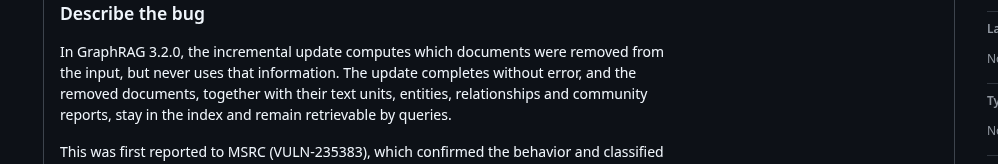
The reference implementation of GraphRAG shows the same problem at the plumbing level. An issue filed on 5 October describes what happens when you delete source documents and run an incremental update: the documents, “together with their text units, entities, relationships and community reports, stay in the index and remain retrievable by queries.” In the reporter’s test, local search recovered 77% of the removed people’s unique facts, “the same as before the removal.” After a full re-index it recovered none, although the cache and update backups still contained them. Microsoft’s security response team, the reporter says, classified it as a “functional and data-lifecycle defect rather than a security vulnerability.”
| Measure | Value |
|---|---|
| Before removal | 77% |
| After incremental update | 77% |
| After full re-index | 0% |
Source: microsoft/graphrag issue 2590 (filed 5 October 2026), one test with 7B-class model on a small corpus. An independent bug report, not a controlled study.
Graphiti handles facts that change over time better than most, with edges that carry validity intervals. But invalidation fires only when a language model judges that a new edge contradicts an old one. An AngelList engineer, writing about their semantic layer, puts the cost of staleness in one line: “stale semantics are worse than none. They’re confidently wrong.”
What survives both
The fix is not “no graph”. Keep a central graph, and be strict about what it holds.
- Centralise the map. Entities, definitions, owners, lineage, and decision records with validity intervals. This is metadata, and it changes through reviewed pull requests, the way Anthropic’s skills do.
- Do not centralise the territory. Content, and any claim a model wrote about content, is fetched at read time using the asking user’s own token. OpenFGA describes the pattern for retrieval: for each candidate document, check whether the user can view it, and pass only the survivors to the model. Glean’s connector documentation also describes live tools that “retrieve current data or perform actions at request time”, alongside its indexed content.
- Treat any cache as a cache. Anything derived and stored carries the IDs of its sources and a permission version that is checked when it is reused.
- Give every answer a provenance line. Source, freshness and owner, so a wrong number can be traced to a person.
The trade-off is real. Google’s Gemini Enterprise documentation says that with federation “data isn’t copied into the Gemini Enterprise index”, and then: “However, because the data is not indexed, search quality might be lower.” A central index can rank across everything at once, and a federated one cannot. I think that is the right trade for sensitive data, and the wrong one for a public wiki.
What would change my mind
Palantir’s Foundry documentation says a marking “will immediately be inherited along all file and data dependencies.” That is the counter-example. A central store can keep derived-data access correct when every derivation is a tracked transform inside one platform, so lineage is complete. The arXiv paper shows the same thing in a lab. The case I could not find is a GraphRAG-style system where each derived node inherits the intersection of its sources’ permissions, revocations stream in, deletes are real, and leakage stays near zero under realistic group churn. If that ships, with measurements, this post is out of date.
Until then: a context graph needs an owner, an update path for deletes, and a way to ask “who is asking?” at the moment of the question. Without those it is a snapshot with a confident voice.
References
- Context graphs: AI's trillion-dollar opportunity Foundation Capital, 22 December 2025.
- Querying a Cortex Search Service Snowflake documentation.
- Salesforce connector: about Glean documentation.
- Access control in Azure AI Search: query-time enforcement Microsoft Learn.
- Cognee issue 5520 GitHub, 8 October 2026.
- Graphiti issue 1679 GitHub, 21 September 2026.
- Lineage-gated agent memory arXiv, 5 October 2026.
- Incremental update does not remove deleted documents (issue 2590) microsoft/graphrag on GitHub, 5 October 2026.
- How Anthropic enables self-service data analytics with Claude Anthropic, 3 June 2026.
- Authorization for RAG OpenFGA documentation.
- The semantic layer nobody maintains AngelList, 28 August 2026.
- Markings Palantir Foundry documentation.
- Introduction to connectors and data stores Google Cloud documentation, 14 October 2026.
- Consistency in SpiceDB AuthZed documentation.
- AI Search (limitations) Databricks documentation.
- Permissions: datasets Cognee documentation.
- Data and privacy for Microsoft 365 Copilot Microsoft Learn.